I build AI systems that know when not to act. Most of my work is RAG and LLM infrastructure - retrieval, vector storage, and model routing. I own the whole thing: decisions, features, deploys, monitoring, and the stuff that breaks after launch.
Right now I run five AI products in production, with no team behind them: Sentinel, Cutline, RepoDoc, VectorMail and Visura. I built every layer of every one, and I'm the only person on call for them. Cutline has been running since March: 85 signups, all inbound, and a first paying customer in September, with no ads run.
I'm looking for a full-time role at an early-stage startup where I own real systems and deliver without hand-holding: remote on US/EU hours, in-office in Bengaluru, or relocating to Germany. Hand me the problem and the constraints, and I'll take it from design through deploy and on-call. I reply within 24 hours to anything real. Say hello.
A revenue-intelligence backend whose first question is what it's even allowed to read. Email, calendar, and chat are ingested only when a participant matches a contact synced from your CRM - read-only, fail-closed, and PII-blind.
One sentence in, one finished MP4 out - directed by a pipeline of up to 12 stages per slideshow, not a template engine. It infers audience, goal, tone, and arc; plans 1-3 shots per story beat, with more beats for longer videos; sources or generates imagery; composes the render. No templates, no creative knobs.
Ask an unfamiliar repo questions and get grounded, cited answers. Retrieval runs over what each file means - LLM summaries embedded, not raw code - indexing is a durable Postgres lease queue that survives serverless limits, and each answer's estimated model cost is recorded per project.
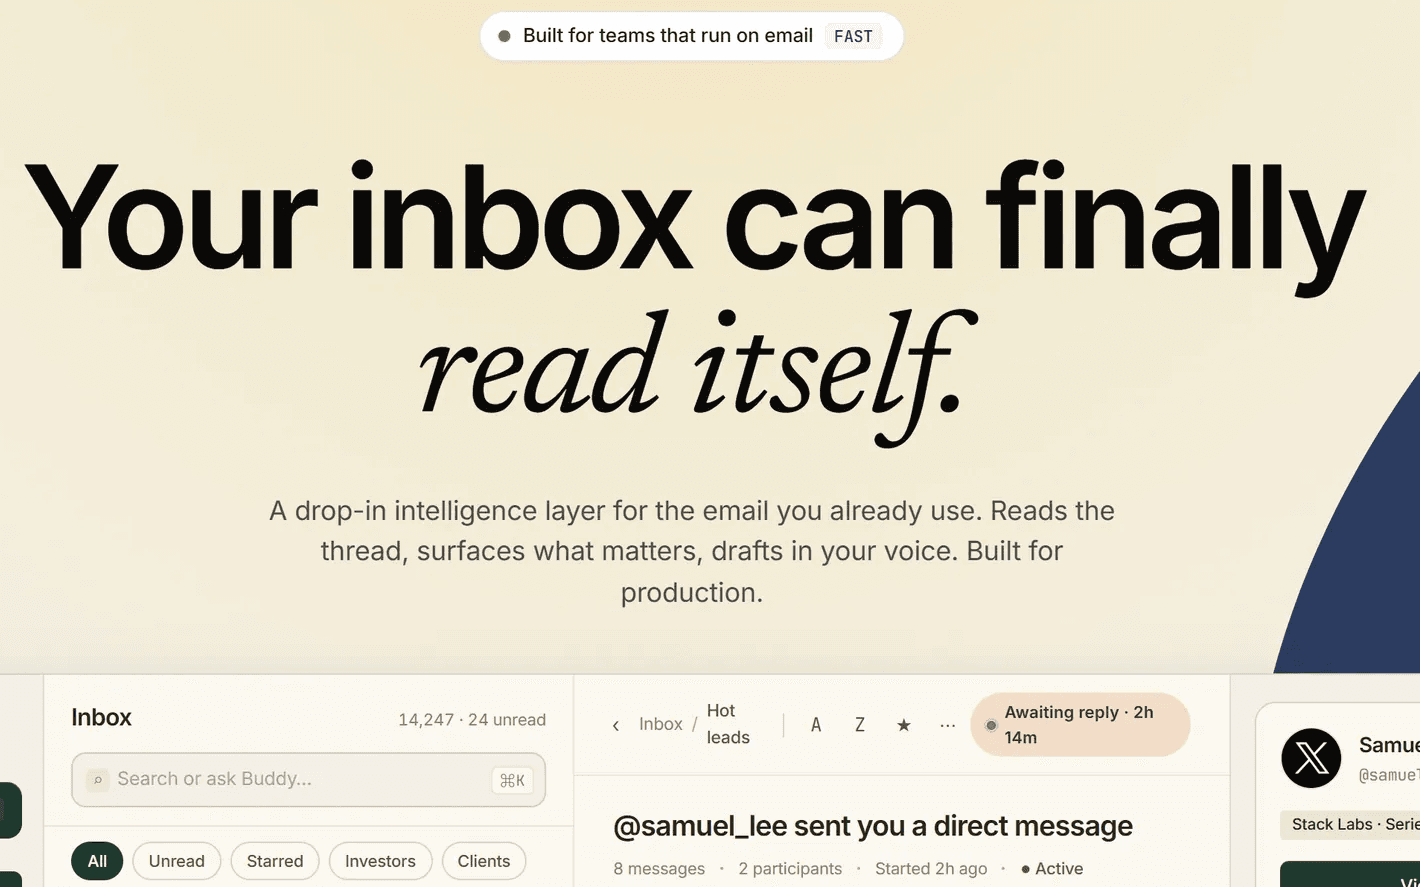
Reads your inbox, drafts follow-ups, and sends them. Deterministic rules pick the threads: a reminder is due, or the last message came from an external sender and you haven't replied. Rules also decide whether each follow-up sends, waits for your approval, or is dropped; the LLM only writes the draft. Inbox and embeddings live in one Postgres, with no separate vector store.
Shows what changed between two versions of a document, in your browser, with no upload and no model. Passage boundaries come from each sentence's own hash, so an edit near the top doesn't shift the rest, and a re-upload re-summarizes only what changed. The LLM only explains changes the hashes found, and drops any explanation it can't quote from the document.
19 of 20reused after a one-line edit
12 re-exportsall read as zero changes
No uploadand no model to compare
Verbatim quoteor the explanation is dropped
Stack
27 tools and 4 practices
Layer 1 Frontend (Product UI)
TypeScript
React
Next.js (App Router)
Tailwind CSS
Remotion
Layer 2 Backend & APIs
Node.js
tRPC
Zod
WebSockets
Dodo Payments
Clerk
Better Auth
Layer 3 AI Systems (Production)
OpenAI
Claude
Gemini
OpenRouter
RAG pipelines
pgvector
Layer 4 Data & Infrastructure
PostgreSQL
Prisma
Redis
BullMQ
Object Storage (S3)
Layer 5 Cloud & Deployment
AWS
Docker
Vercel
CI/CD (GitHub Actions)
Architecture & Practices Across every layer
Distributed systems
Event-driven design
Multi-tenant SaaS
Cost optimization
Walkthroughs
Walkthroughs I recorded on Loom for Sentinel, Cutline, RepoDoc and VectorMail, each 11 to 14 minutes long. Open any one to watch.
Independent / Engineering for early-stage startups · Remote
Full ownership of system design, feature delivery, reliability, and iteration - everything here built, deployed, and maintained by me.
Owned backend services, data stores, AI pipelines, and deployment infrastructure, including authentication, payments, and third-party integrations. Debugged production incidents, performance bottlenecks, and scaling limits while deploying continuously without breaking live systems.
Thanks for scrolling all the way down here. I'm open to full-time roles at early-stage, AI-first startups: remote, in-office in Bengaluru, or relocating to Germany. If that's you, let's work together.


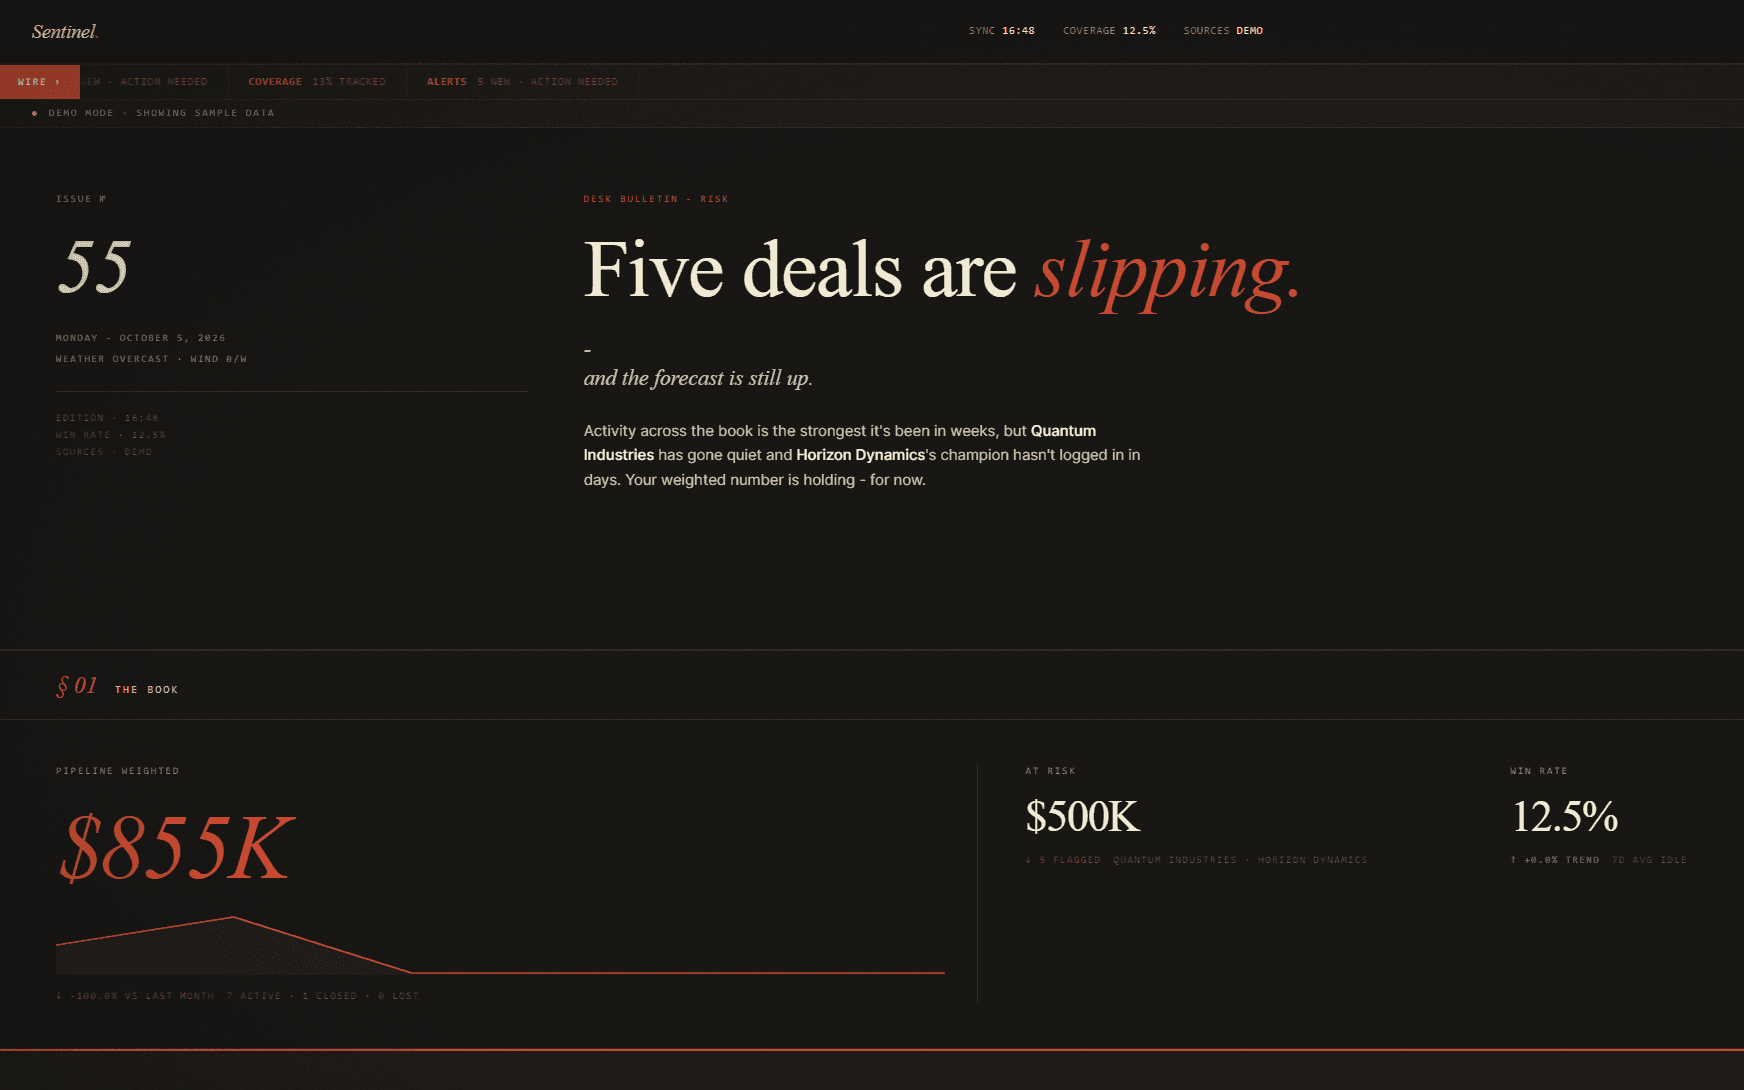
 Sentinel
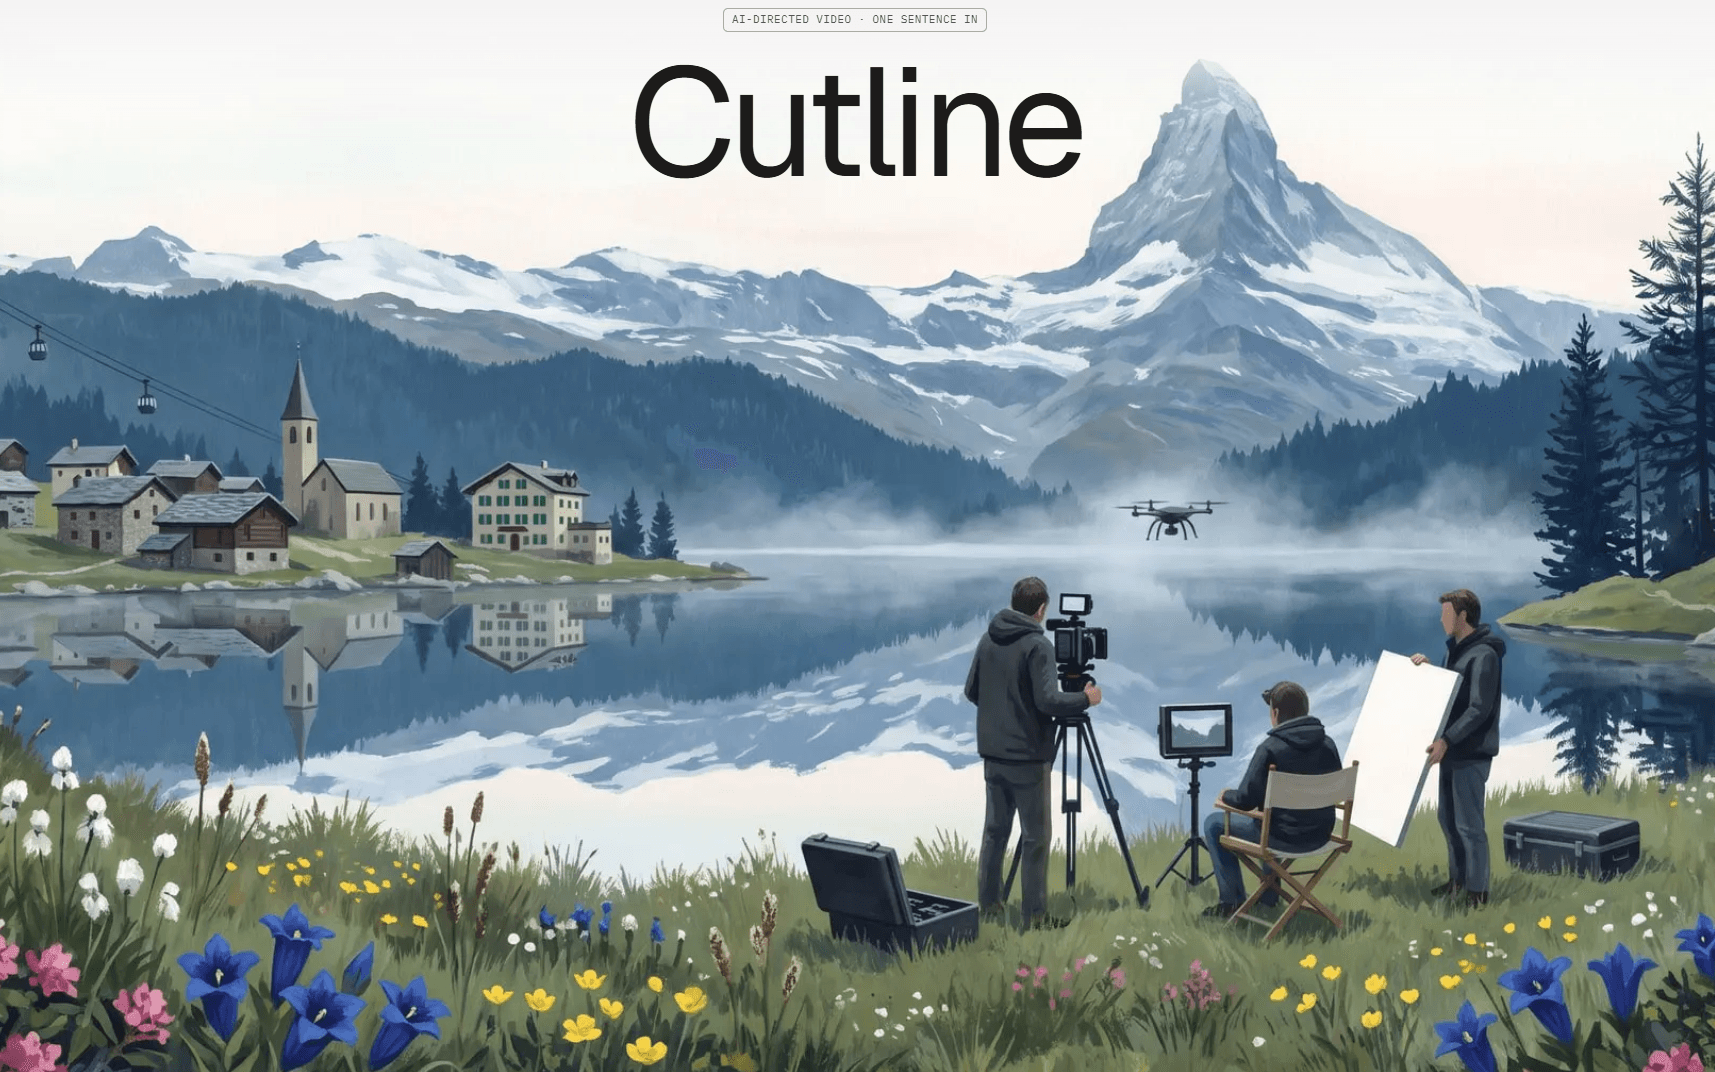
 Cutline
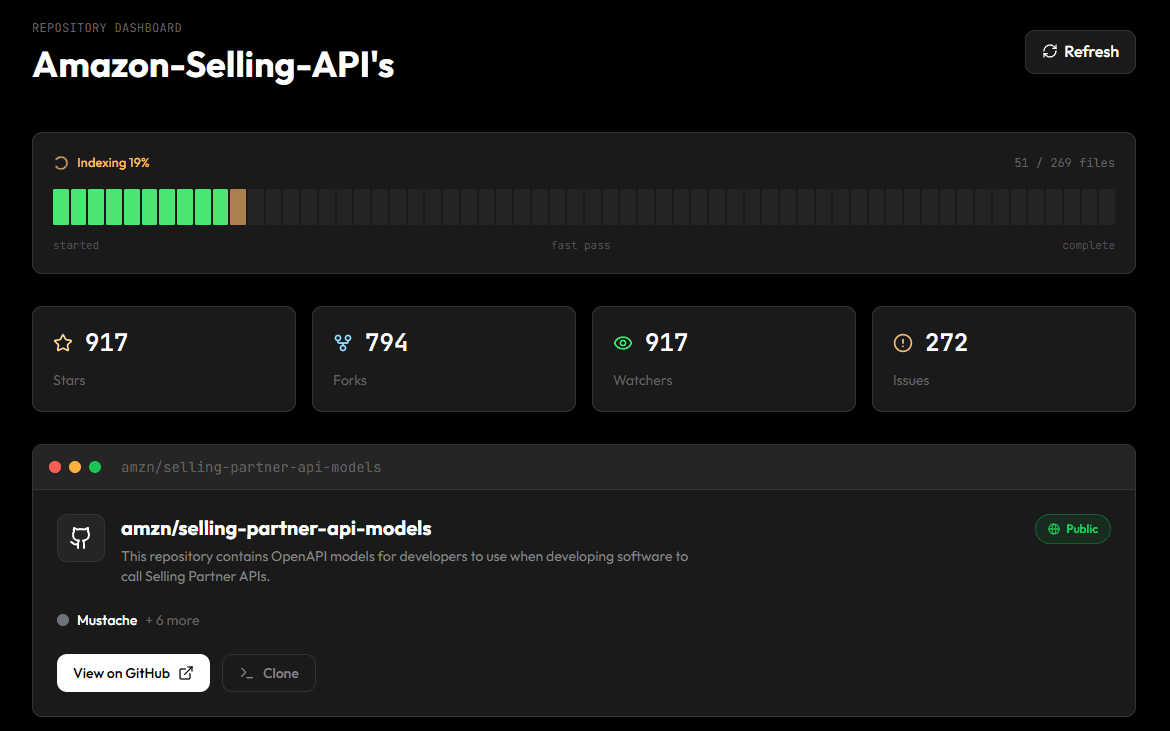
 RepoDoc
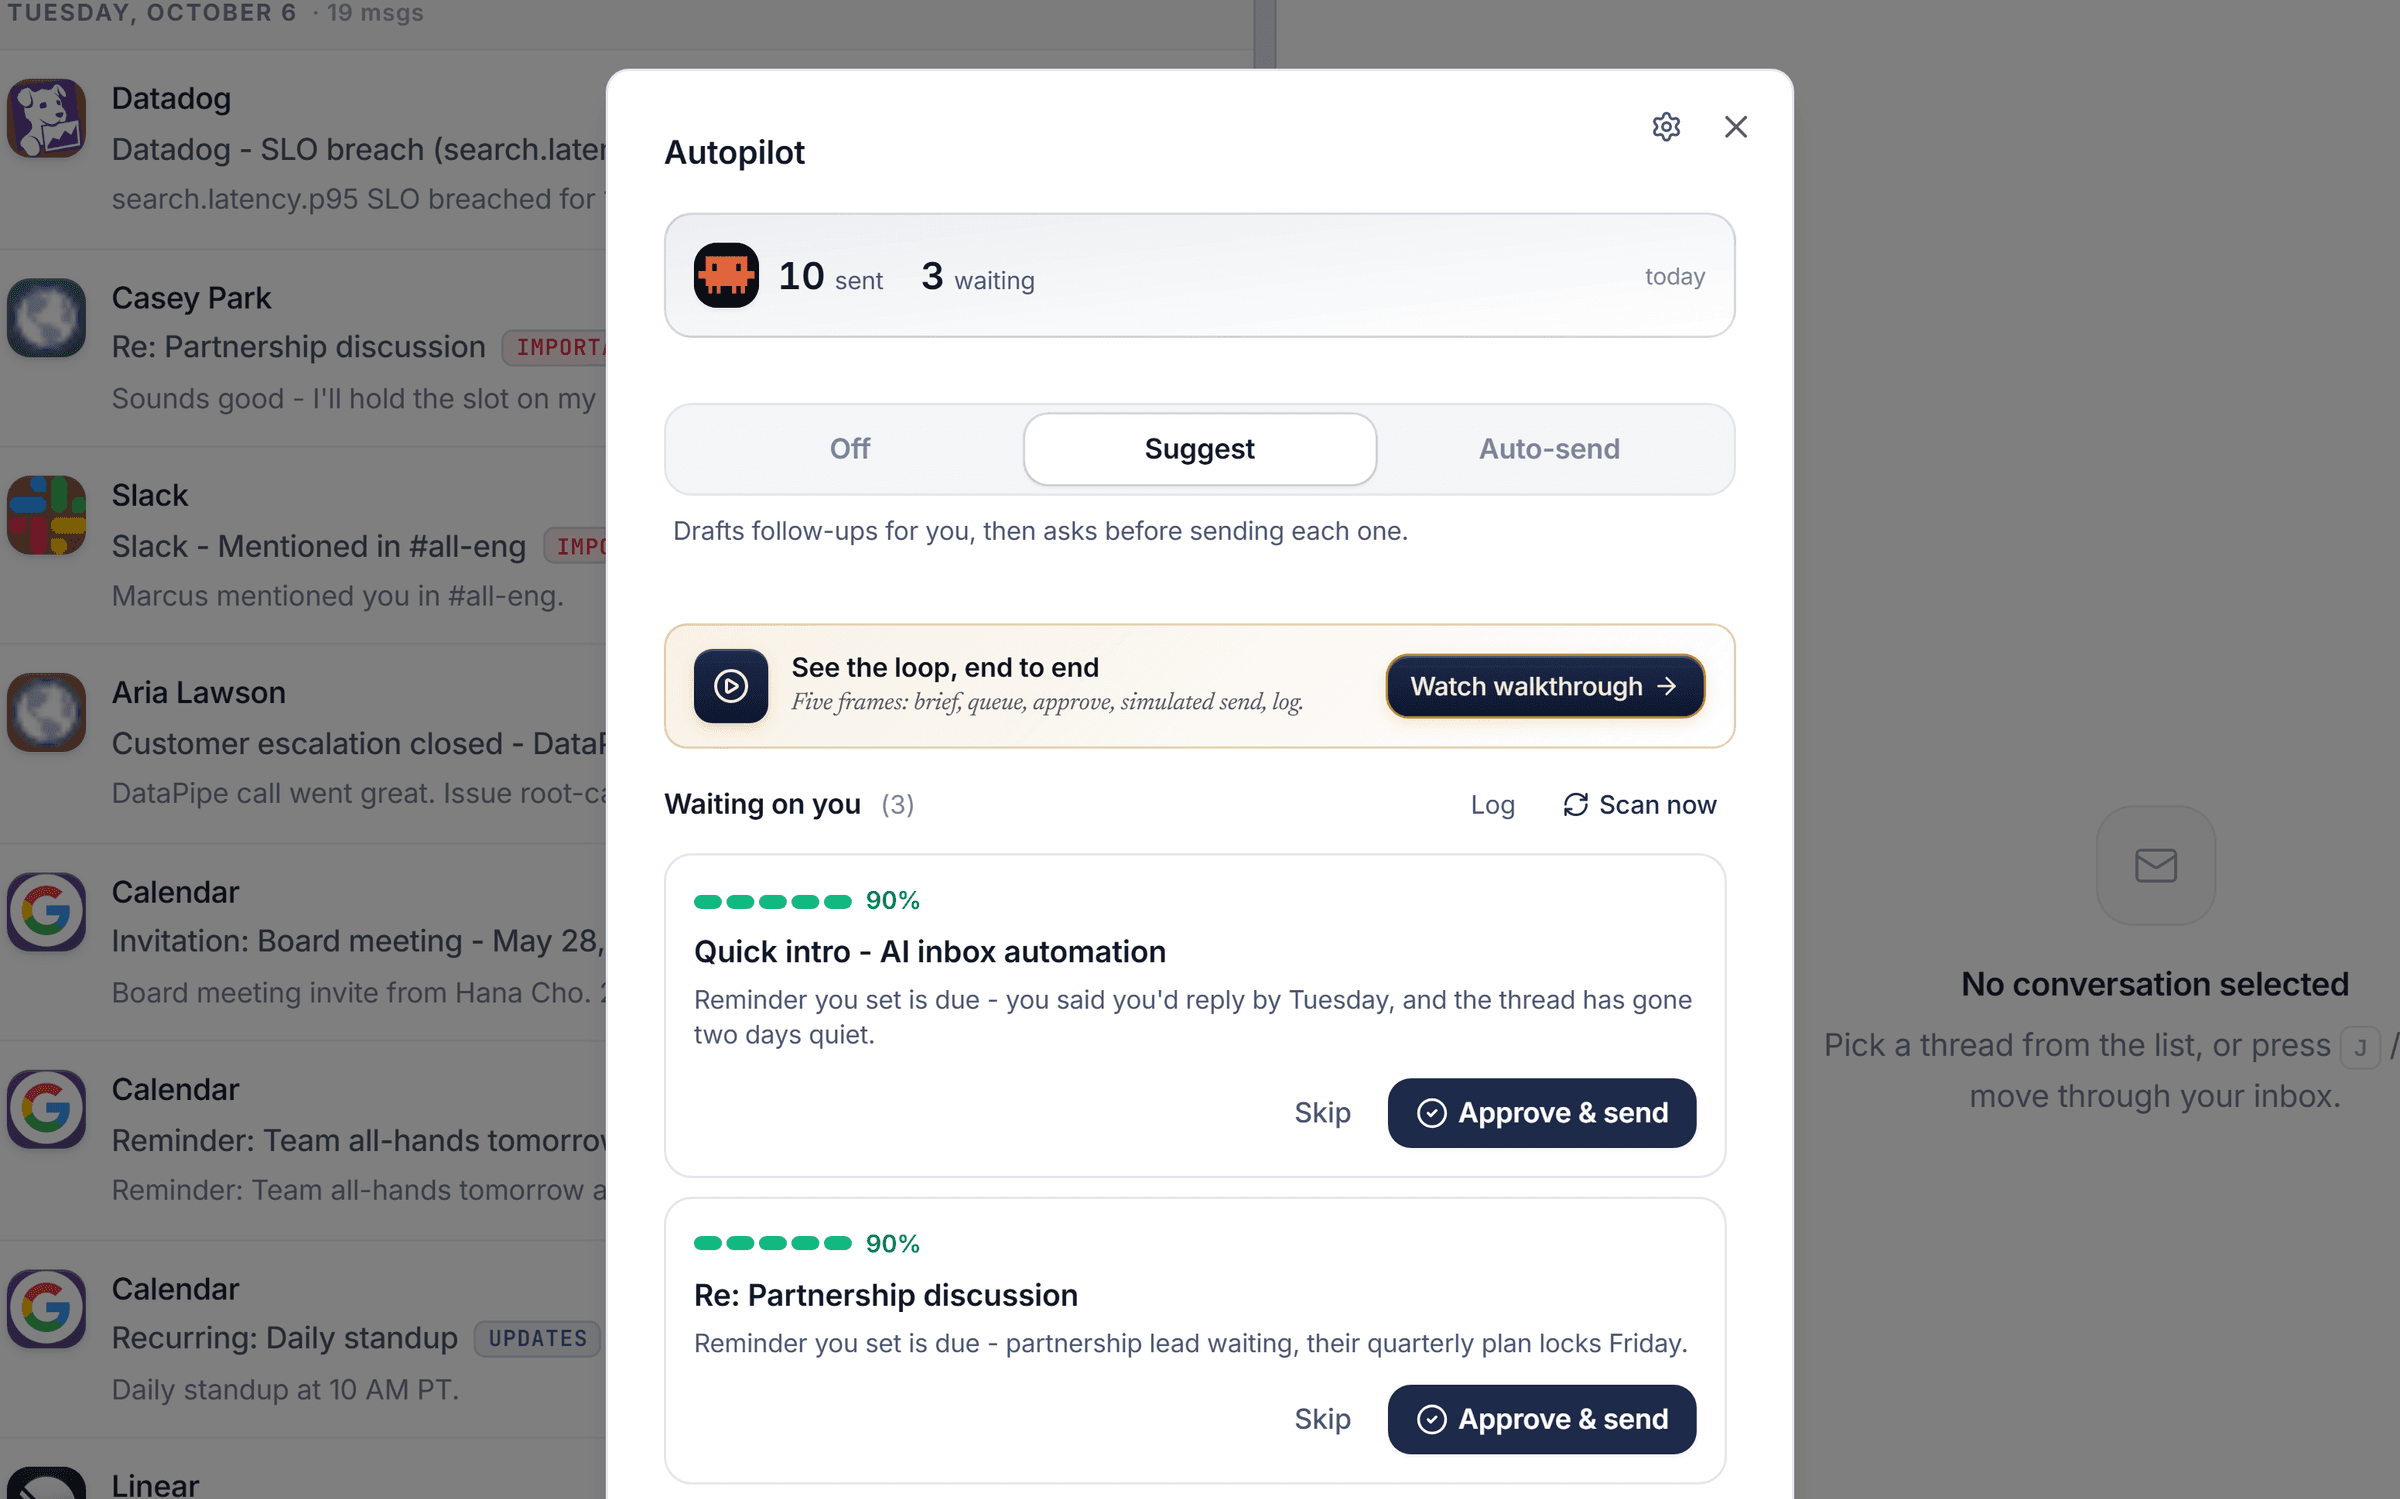
 VectorMail
 Visura

 Sentinel
 Cutline
 RepoDoc
 VectorMail
 Visura

